The recommended approach combines financial-statement benchmarking (FSB) as the primary screening filter with targeted valuation- or product-market overlays, then validates the resulting peer set with out-of-sample backtests. Choose the FSB decomposition that matches the metric under review: income-statement overlap for earnings work, balance-sheet overlap for leverage and net-debt work. A forensic analytics platform applies disclosure-first logic when building sector benchmarks and per-company forensic reports.
TL;DR:
- Peer selection should be based on objective-specific similarity measures, such as income statement overlap for earnings and text similarity for business description.
- Building a defensible peer group requires multiple similarity scores, operational filtering, and thorough documentation of thresholds and parameters.
- Validation involves sensitivity analysis, predictive power checks, and transparent reporting to ensure the peer set remains robust under different scenarios.
- Different types of peers suit different metrics; valuation distance is best for market perception, while balance sheet similarity fits leverage and capital structure KPIs.
- Platforms can automate the process, providing sector benchmarks and forensic reports that are directly auditable and save analysts days of manual work.
Table of Contents
- What Is Peer Benchmark Methodology?
- A Step-by-Step Workflow for Selecting a Peer Group
- How Similarity Measures Are Calculated
- Matching Peer Selection to the Metric You Are Benchmarking
- Validating a Peer Group Before You Trust It
- How Lacuna Index Applies This Methodology
- Where Peer Benchmarking Breaks Down in Practice
- Put This Methodology to Work Without Building It From Scratch
- Sources
- FAQ
What Is Peer Benchmark Methodology?
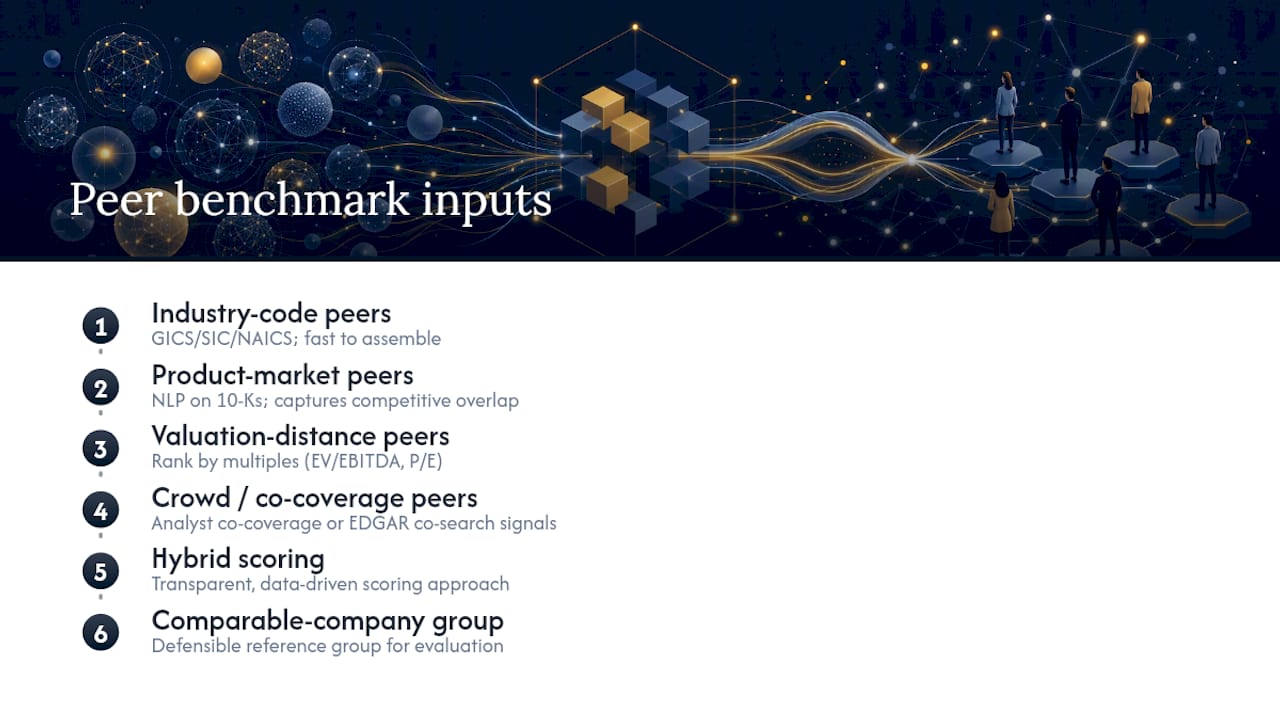
Peer benchmark methodology is the systematic process of identifying comparable firms and using their financial or operational data to evaluate a target company's performance, valuation, or execution against a defensible reference group. The discipline rests on one hard truth: the quality of any benchmarking conclusion is bounded by the quality of the peer group feeding it. Four broad families dominate current practice; each solves a different problem.
Industry-code peers group firms by GICS, SIC, or NAICS classification. They are fast to assemble and universally understood by committees, but a single four-digit code can lump together firms with wildly different business mixes, disclosure habits, and capital structures. Industry codes are a starting filter, never a finish line.
Product-market and text-similarity peers use natural-language processing on 10-K filings, embeddings, or tools like the Hoberg-Phillips TNIC database to measure how similarly two companies describe their business. This approach captures competitive overlap that industry codes miss, particularly for conglomerates or newly categorized sectors.
Valuation-distance peers rank candidates by proximity in multiples (EV/EBITDA, P/E) or by warranted-multiple models tied to growth, margin, and risk drivers. This method aligns naturally with value-driver approaches to comparable-firm selection, which can outperform industry-only peers for valuation tasks specifically.
Crowd and co-coverage peers infer comparability from analyst co-coverage or EDGAR co-search behavior. A comparative study of six peer-identification schemes found that crowd-based schemes work best when the crowd is sophisticated and the firm's information environment is already transparent. That conditionality matters: crowd signals degrade for thinly covered, multi-segment, or opaque issuers.
Most rigorous benchmarking work hybridizes these families rather than picking one exclusively, following a transparent, data-driven scoring approach to enhance methodological clarity.
A Step-by-Step Workflow for Selecting a Peer Group
Building a defensible, reproducible peer group follows a fixed sequence. Skipping steps, especially the documentation step, is how peer groups become impossible to defend under scrutiny.
- Define the objective and the benchmark metric first. Decide whether the analysis targets earnings, net debt, valuation multiples, or an operational KPI, because that choice determines which similarity measure to weight most heavily later.
- Assemble an initial candidate pool. Combine industry classification, revenue-size bands, and rough product-market overlap to generate a broad long list, typically 20 to 40 names.
- Score candidates on disclosure-overlap and other similarity measures. Compute FSB/Jaccard scores, text similarity, and valuation distance for each candidate against the target firm.
- Apply operational filters. Drop names with insufficient trading liquidity, incomplete disclosure histories, or thin analyst coverage that would undermine the crowd signal.
- Run sensitivity checks and document every parameter. Record the peer count, weighting scheme, and inclusion thresholds used so another analyst can reproduce the exact peer set.
Pro Tip: Keep a version-controlled log of every parameter choice, threshold, and excluded candidate. When a governance committee asks why Firm X was dropped, "the FSB score fell below our 0.35 threshold" is a defensible answer; "it felt like a bad fit" is not.
How Similarity Measures Are Calculated
Financial-statement benchmarking, or FSB, is typically computed as a pairwise Jaccard similarity coefficient: the number of overlapping reported line items divided by the total number of line items across both firms minus that overlap. Research decomposing FSB by statement shows a sample pair scoring 0.69 overlap, and the score can be calculated separately for the income statement, balance sheet, and cash-flow statement rather than as one blended figure.
That decomposition carries real predictive weight.
A one-standard-deviation increase in income-statement FSB improves earnings-forecast accuracy by 17.3%, while balance-sheet FSB improves net-debt forecast accuracy by 12.1%.
The other measures each capture something FSB cannot:
- Text similarity (TNIC-style or embedding-based) measures overlap in business descriptions; preprocess filings by stripping boilerplate legal language before comparing, or the score gets diluted by generic risk-factor text.
- Valuation distance normalizes multiples (EV/EBITDA, P/E, P/B) against growth and margin, then measures Euclidean or rank distance between the target and each candidate.
- Co-coverage/co-search measures count shared analyst coverage or EDGAR search co-occurrence; effectiveness depends heavily on analyst attention and firm size, so treat this as a supplementary signal, not a primary filter.
Combine these into a composite score by normalizing each measure to a 0 to 1 scale, then weighting according to the benchmarking objective; practitioner guidance consistently stresses validating those weights with out-of-sample testing rather than assigning them by intuition.
Matching Peer Selection to the Metric You Are Benchmarking
The single most common analyst error is applying one peer group to every question. A peer set built for valuation work is not automatically the right peer set for a leverage analysis.
- Income-related KPIs (revenue growth, margin, EPS) call for peers ranked primarily by income-statement FSB and product-market text similarity.
- Balance-sheet and leverage KPIs (net debt, coverage ratios, capital structure) call for peers ranked by balance-sheet FSB and size or capital-structure filters.
- Valuation comparisons require valuation-distance peers alongside market-perception signals like co-coverage, since multiples reflect how the market prices comparable risk and growth.
- Operational or process KPIs benefit from process-execution benchmarking using standardized event logs rather than financial-statement overlap, since the comparison target is workflow efficiency, not accounting data.
Validating a Peer Group Before You Trust It
A peer group is a hypothesis until it is tested.
- Run sensitivity analysis on peer count, weighting scheme, and inclusion threshold to confirm the conclusion does not flip with minor parameter changes.
- Quantify disclosure-completeness loss by measuring how much predictive power disappears when low-FSB peers with missing line items are dropped versus retained.
- Report validation results transparently, including the forecast-error delta, the sensitivity range, and the final peer count, so reviewers can judge robustness themselves.
Pro Tip: Vendor methodologies like MetricNet's comparability framework validate peer data against multiple comparability dimensions, scope, scale, complexity, geography. Borrowing that multi-dimensional checklist strengthens any FSB-based validation process.
How Lacuna Index Applies This Methodology
Some platforms build sector benchmarks and per-company forensic reports entirely from public disclosures: earnings calls, SEC filings, proxy statements, and press releases, with no proprietary data or insider access. Disclosure overlap can function as the backbone of comparability scoring, quantifying how a company's execution score and narrative score diverge from sector peers with similar reporting structures. Analysts who want the implementation detail behind this can review the methodology walkthrough or browse sector benchmarks directly.
Where Peer Benchmarking Breaks Down in Practice
The tension every analyst eventually faces is precision versus interpretability. A composite score blending five similarity measures may forecast better, but a governance committee cannot audit five weighted inputs in a ten-minute meeting. Multi-segment conglomerates, firms with thin disclosure histories, and low-coverage small caps are where peer selection fails most often, because FSB and co-coverage both lose signal exactly when you need them most. The fix is not a fancier model. It is presenting the peer rationale as a ranked list with the top two or three exclusion reasons named plainly, then letting the sensitivity results, not the modeling elegance, carry the argument.
— Glen
Put This Methodology to Work Without Building It From Scratch
Assembling a disclosure-overlap peer group by hand, scoring FSB across dozens of candidates, cross-checking valuation distance, documenting every threshold, takes analyst teams days per company. Some platforms run an evidence-based process systematically across covered sectors, publishing execution scores, narrative scores, and disclosure-overlap comparisons that are audit-traceable back to the public filings behind them.

The output maps directly onto the workflow above: sector benchmarks handle peer discovery and disclosure scoring, while per-company forensic reports document the resulting comparability and gap analysis in one place. The Sector Sweep plan covers benchmarking across an entire sector; Cohort Pulse tracks a defined peer cohort over time. Start by reviewing per-company analysis for a name you already follow, or check current plan details on the pricing page.
Sources
- For the Analyst: Peer Benchmarking Methods to Improve Earnings Forecasts
- The Search for Peer Firms (HBS working paper excerpt)
FAQ
What Is Benchmarking Methodology?
Benchmarking methodology is the structured process of comparing an organization's metrics against a defined reference group to identify performance gaps. In finance, that reference group is a peer set selected through disclosure-overlap, product-market, or valuation criteria rather than convenience sampling.
What Are the 5 Phases of Benchmarking?
Most frameworks describe five phases: planning (defining the metric and objective), data collection (assembling candidate peers and their disclosures), analysis (scoring similarity and comparing performance), integration (documenting findings for stakeholders), and action (applying the results to forecasts or decisions). The peer-selection workflow described above maps directly onto the planning and data-collection phases.
What Is Peer Group Benchmarking?
Peer group benchmarking compares a target company's financial or operational metrics against a curated set of comparable firms rather than the broader market. The reliability of the conclusion depends entirely on how rigorously that peer group was selected and validated, which is why disclosure-overlap scoring and out-of-sample testing matter more than the peer count itself.
What Are the 7 Types of Benchmarking?
Common typologies list internal, competitive, functional, generic, strategic, process, and performance benchmarking. For financial analysts, the peer-identification families that matter most in practice are industry-code, product-market/text, valuation-distance, and crowd/co-coverage methods, which map most closely to competitive and performance benchmarking.
Does Lacuna Index Offer Peer Benchmarks for Free?
Sector-level benchmarks from Lacuna Index are publicly accessible, while detailed per-company forensic reports require a paid subscription. Current plan details for Cohort Pulse and Sector Sweep are listed on the pricing page.